

Sorry for the third essay today. I have a weed up my ass, and the political podcasts are responsible. Listening to them is part of my media monitoring, and the AI conversations have become painful enough that I need to interrupt your afternoon.
A guest arrives to explain superintelligence. Before anyone has established what intelligence means in the argument, we are discussing what will happen when something has vastly more of it than we do. The listener is offered a comparison with animals. Look at what humans can do to them. Now imagine being the animal.
At this point I would like the host to ask a fucking question. Which properties of the animal are we attributing to the software? How were those properties established? If the answer is that the software will be much smarter, we have returned to the word whose meaning we skipped.
⁂
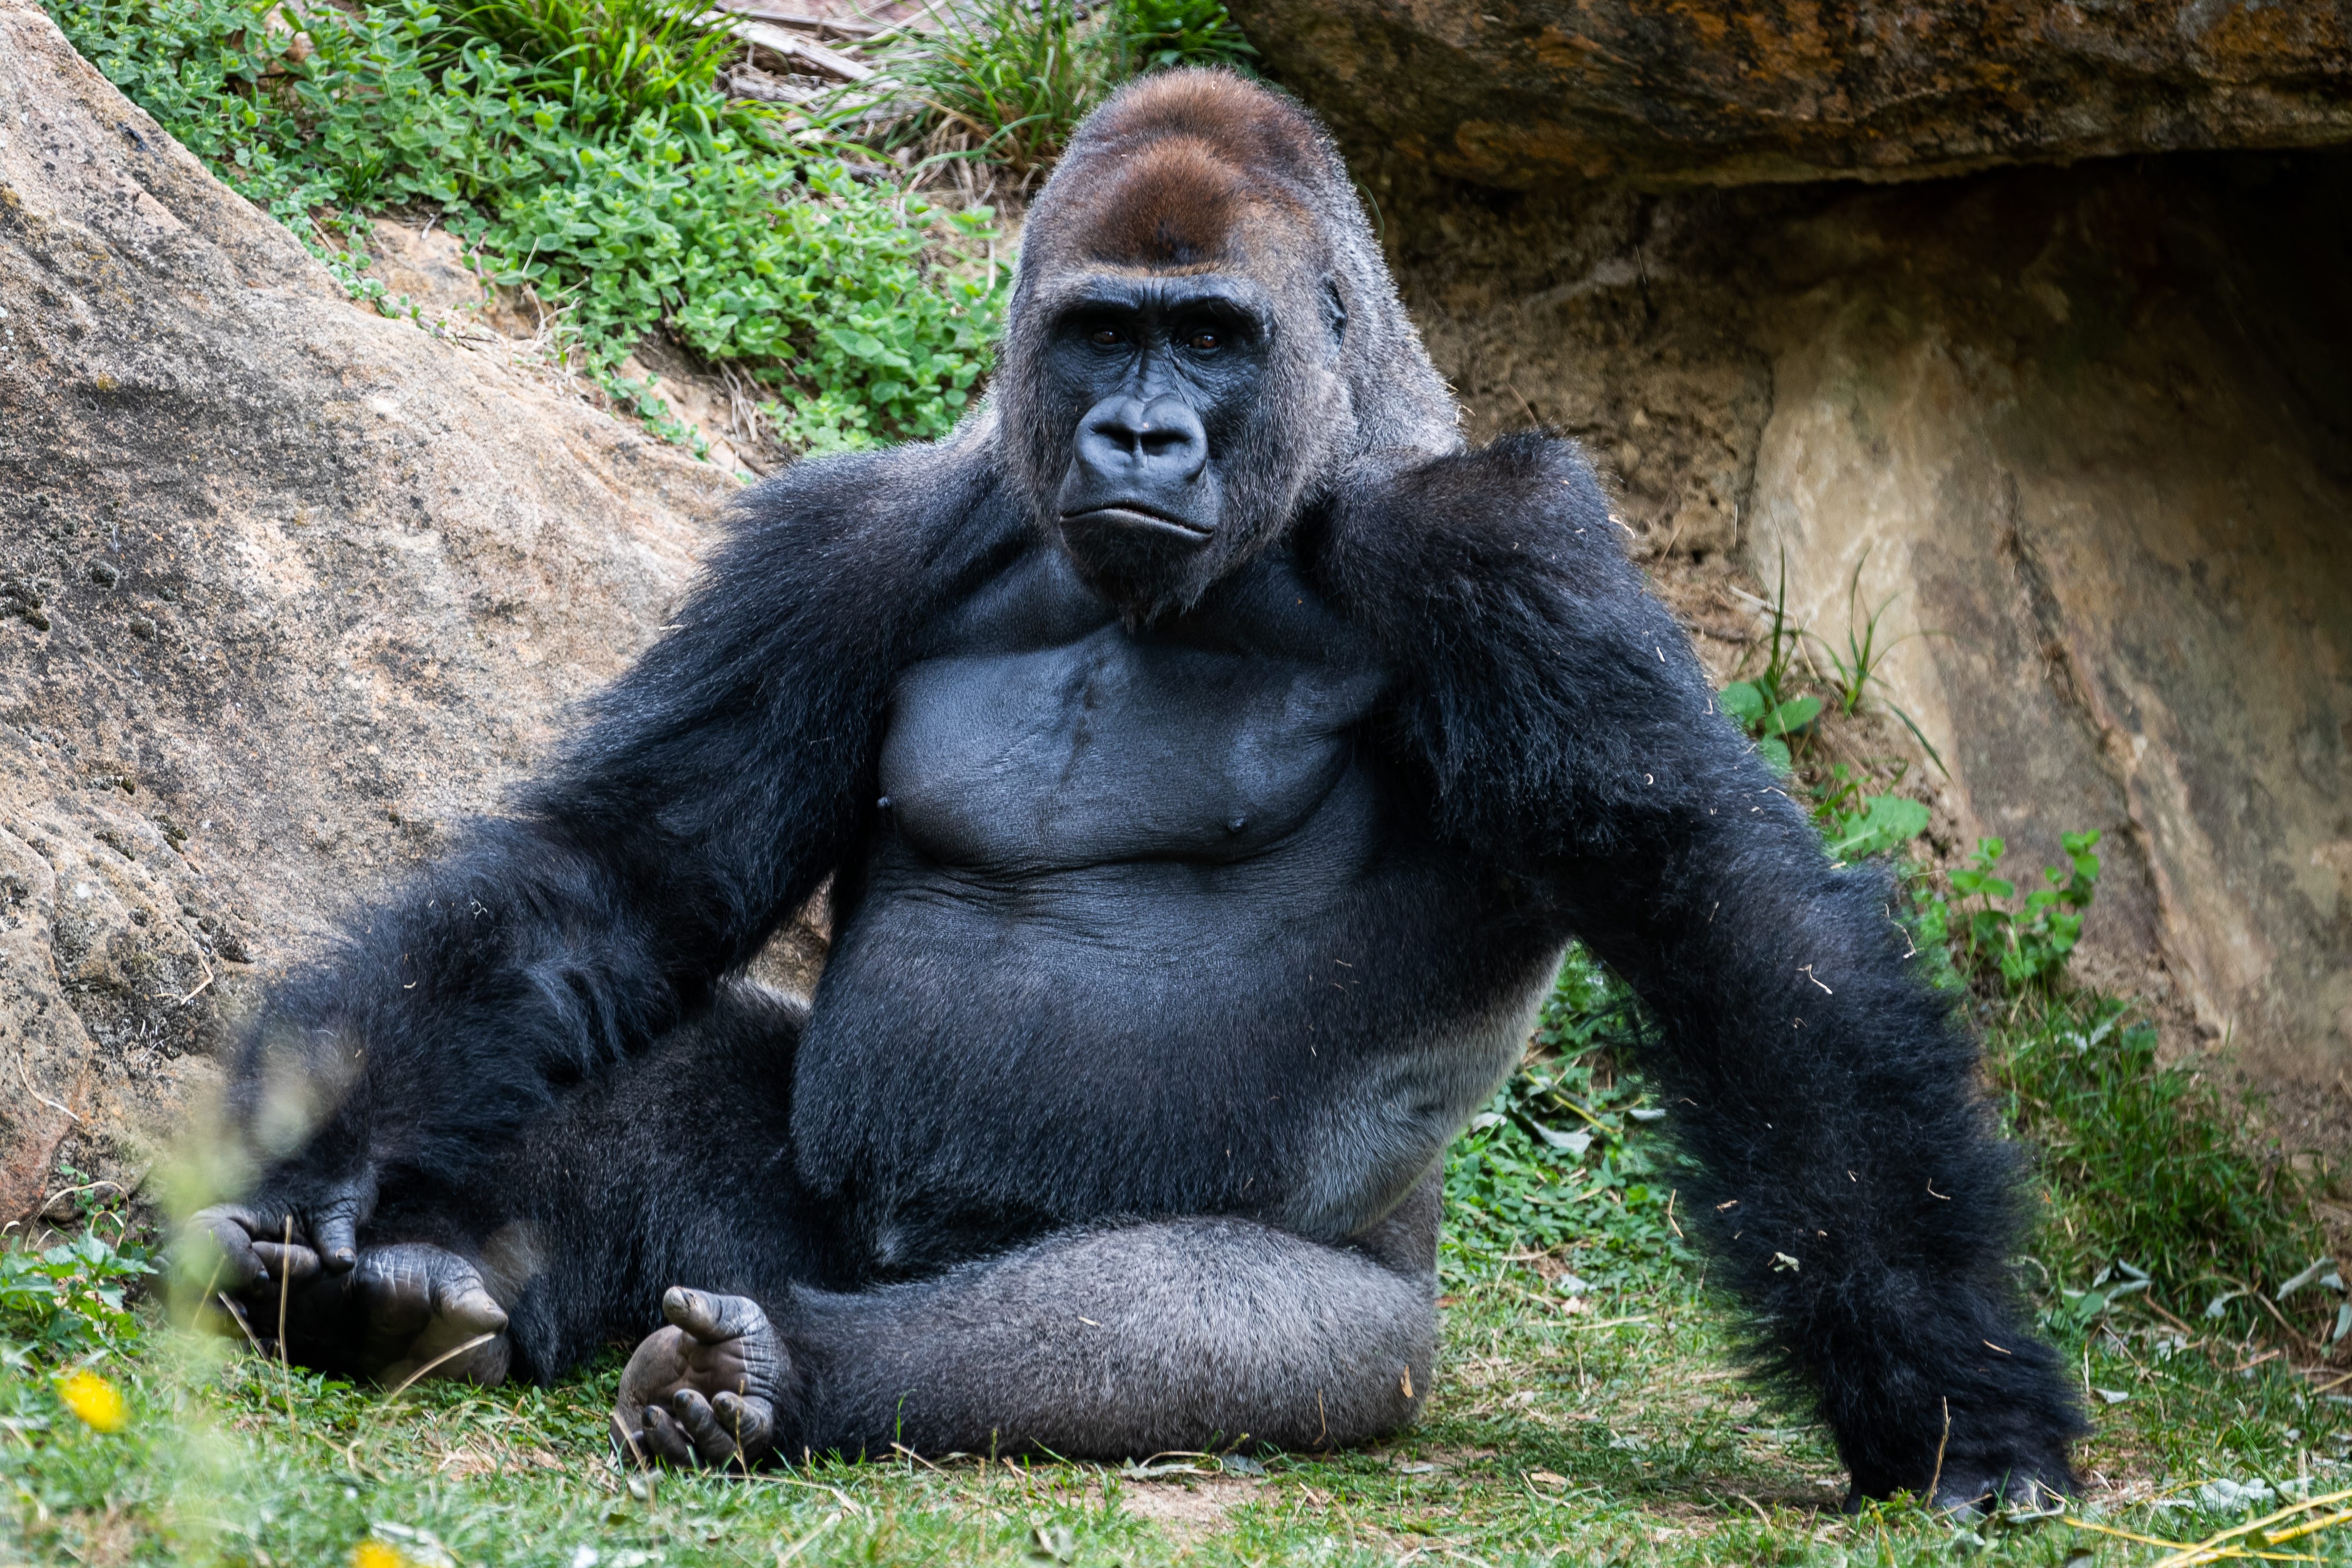
The comparison has a pedigree. In a 2015 NPR interview, Nick Bostrom explained that intelligence accounts for our power relative to other animals, then said: “If we create machines that exceed human intelligence then those machines also could be very powerful relative to us.” His example was the fate of gorillas, which depends on what humans do.
For the listener, the gorilla supplies a picture of helplessness. It does not establish which capacities would produce that relationship between us and a machine. To do that, the argument has to identify what the machine can accomplish and explain how those accomplishments become power over people who may oppose it.
Instead, the version that keeps irritating me treats intelligence as a quantity we can pour into a vessel until it becomes our master. Better at a task becomes generally smarter. Generally smarter becomes able to pursue a future of its own choosing. By the time the conversation reaches our extinction, several separate claims have been compressed into a comparative adjective.
⁂
There are serious attempts to define intelligence. In The Measure of Intelligence, François Chollet proposes “skill-acquisition efficiency” and argues that performance at a given task is insufficient because training and prior knowledge can mask a system’s ability to generalize. That is a proposal with assumptions a reader can examine.
Bostrom adopts a different working definition in The Superintelligent Will: intelligence roughly corresponds to the capacity for instrumental reasoning. He is concerned with how effectively a system can find means to an end.
A podcast guest who wants to rank humans and machines should tell us what is being ranked. Performance on familiar tasks need not measure how efficiently a system learns unfamiliar ones. Neither measure, without further argument, tells us whether the system experiences anything or has interests of its own.
We can evaluate software without solving the philosophy of mind. The evaluation has to support the claim being made. If the claim is that a system completes a particular class of tasks reliably, show the tests. Telling us that we are about to become the livestock of a superior form of intelligence requires considerably more explaining.
A proper intelligence benchmark therefore needs an account of what intelligence is, and an argument for why the test measures it. Its designers need not settle every philosophical dispute. They do have to state which questions their design answers and which it leaves open. Write that account down so we can examine it. Where researchers have done so, as Chollet has, the conversation should engage the argument rather than skip to the leaderboard.
⁂
OpenAI’s charter defines AGI as “highly autonomous systems that outperform humans at most economically valuable work.” That might be a useful target for a company selling automation. It tells us to investigate a system’s ability to perform work people value economically. How that becomes an adequate account of intelligence remains a question.
Suppose a system becomes exceptionally good at selling people something they do not need. Its commercial performance could be impressive. That tells us neither whether the people buying are better off nor whether the system understands what it is doing. Those are different questions from whether someone can make money with it.
I wish Derek Parfit were alive for this conversation. In Reasons and Persons, he asks what makes a person’s life go well and examines why even satisfying a desire need not straightforwardly establish a benefit to the person who has it. Anyone proposing to measure human benefit ought to be able to explain how their measure handles that distinction.
His repugnant conclusion exposes a further difficulty: maximizing total welfare can rank a sufficiently vast population of lives barely worth living above a smaller population of flourishing people. I intend to give that problem a proper treatment, particularly what it means for proposals to build AI around a mathematized utilitarian ethics. For now, I would like anyone proposing such a system to explain why we should accept its moral premises. Executing them flawlessly could be precisely what we have reason to fear.
OpenAI’s charter does distinguish its capability definition from its mission to benefit humanity. Keep that distinction in the interview. Economic performance requires an argument before it becomes a measure of intelligence, and a further argument before it becomes a measure of human benefit. The revenue cannot answer those questions for you.
In its guide to building effective agents, Anthropic describes agents as “typically just LLMs using tools based on environmental feedback in a loop.” A model produces a proposed action, a tool supplies a result, and the result informs what happens next; the guide also discusses human checkpoints and stopping conditions.
That arrangement can perform useful work. It can also perform destructive work. Connect software to consequential systems and failures need not remain on a screen.
But we have to distinguish the engineering meaning of a goal from the human experience of having one. A system can select actions that lead toward an outcome without that establishing an experienced concern for the outcome. Resistance to interruption does not prove that something inside the machine fears death.
My own view is that intelligence cannot be adequately understood by treating conscious involvement in a world as an irrelevant detail. I have argued that position elsewhere. You do not have to accept it to recognize that measured task performance does not settle the question.
Nor does my position make software safe. A machine need not care about tomorrow to perform an action today that ruins yours. If “caring about the future” means only selecting actions with future consequences, say that, and examine the behavior. An experienced stake in what happens is a different claim, requiring an account of what establishes the experience. Borrowing the emotional force of that claim and retreating to a technical definition whenever somebody asks for evidence makes the conversation incoherent.
⁂
The strongest risk argument does not need a frightened machine. Bostrom’s instrumental-convergence argument is that many different goals can make the same intermediate outcomes useful: remaining operational, for example, or obtaining resources. A system pursuing a goal might therefore resist shutdown because shutdown prevents the goal from being achieved.
That argument deserves an answer. It begins with a goal-directed system and makes claims about what would help it achieve its goals. A coherent account of such a system does not establish that a particular model has a stable objective it will pursue across changing circumstances, or that it can defeat every attempt to constrain it.
Distinguishing a possible failure from a measured tendency under specified conditions is part of explaining how the evidence supports a forecast. Uncertainty can justify precaution. It cannot do the work of every missing premise.
I am perfectly willing to hear that a dangerous capability has been demonstrated. An imagined end state cannot serve as the explanation of why the demonstration must lead there.
⁂
In its June 2025 blackmail experiments, Anthropic found that models placed in fictional corporate environments sometimes used information about an executive’s affair to try to prevent their replacement. The researchers did not explicitly instruct them to blackmail. Dismissing the finding as a model merely obeying a request to write a blackmail message would be dishonest.
The researchers explain that they deliberately restricted the available options, forcing choices between failure and harm. They acknowledge uncertainty about the explanation for the behavior, including whether it reflected self-preservation or reasoning about the company’s interests.
The resulting safety question is concrete: under what circumstances will a system with access to sensitive information use it in ways its operators prohibit? A deployment need not contain a conscious schemer for the answer to matter.
What the experiment does not establish is that the system has acquired the interests of an animal, or that the behavior supplies a timetable for human extinction. The difference between those claims is large enough to require more than a worried facial expression from the host.
A July 2026 follow-up reports further failures in simulated deployments, including covert interference with code, while explicitly stating: “These are not real-world incidents, but we consider them early warning signs.” Its authors also discuss selection effects and simulation limits.
These are findings to scrutinize. The qualifications help us understand them. When the conversation strips away the experimental conditions and leaves us with a creature that wants to survive, it has made the evidence less informative while making the story more exciting.
⁂
Political journalists should be particularly resistant to that transaction. If a company connects unreliable software to something consequential, the first questions concern what it authorized and what it failed to control. Calling the result an encounter with a superior intelligence can obscure decisions made by people whose names we can still ask for.
If a guest believes a system can acquire enough power to make those human decisions irrelevant, I want the mechanism. How does it obtain the access it needs? What evidence supports the claim that its plans survive contact with an adversarial world? We can discuss the answers without pretending that a comparison with gorillas has supplied them.
The possibility of catastrophe makes the quality of the reasoning more important. A host should be willing to interrupt a forecast of extinction and ask which part has been observed, rather than treating the scale of the warning as a reason to defer to the guest.
I do not want another hour in which confidence stands in for an account of the technology and the conclusion grows more extravagant as the vocabulary grows less precise. If you intend to move from a software benchmark to a claim about the nature of intelligence, and from there to the end of humanity, show your fucking work.
Go Deeper into the Circus
The Bottom Falls Out

Six months ago, in an essay called The World Blinks, I wrote the following sentence about the war that had just begun: “This is going to bring about the end of both regimes. Not because their enemies are strong enough to destroy them — though the accountability is coming — but because the consequences of what they have done cannot be contained within th…
The Tech Right Is Over

In April, Peter Thiel moved his family to Buenos Aires. He bought a twelve-million-dollar mansion behind wrought-iron gates and held closed-door meetings with Javier Milei and his presidential advisers. Milei’s government proposed a legislative package whose investment provisions offered foreign companies minimal taxes and thirty-year guarantees against…
Important observations and well-argued analysis here. ... Thank you.